
Hpe Cray Supercomputing Ex Quickspecs Hpe
Search results for fiber, optical network, data center, telecom power and outdoor communications infrastructure topics.
-
High-efficiency UPS system 100kW for supercomputing center use
Highly efficient, easy-to-deploy 100kW, 480V 3-phase UPS that brings best-in-class power protection and low total cost of ownership to edge, small and medium data centers, as well as to critical infrastructure in commercial and industrial applications. A modular, high-efficiency 3-phase UPS that is scalable up to 100kW. Suitable for use in small to medium data centers and high density zones. Enter the total. The Symmetra PX is a world class, redundant, scalable, 3 Phase UPS power protection system designed to cost effectively provide high levels of availability. Includes: Installation guide, Network Management Card, Start-Up Service, User Manual Produk ini saat ini kehabisan stok dan tidak tersedia. Swappable batteries - Allows quick addition of runtime capacity or replacement of existing.
[PDF Version]
-
What are the Huijue AI supercomputing servers
Chinese tech giant Huawei on Thursday unveiled what it described as the world's most powerful "supernode" computer cluster, saying the system delivers top-tier processing power without using Nvidia's advanced chips, the South China Morning Post reported. Speaking at an event in Shanghai, Huawei's rotating. The AI server race heats up as Huawei counters US chip export restrictions. " A super node, also known as Superpod, is a technical architecture used for. Furthermore, 970 will debut in 2028. LineShine has shot to the top of the June 2026 iteration of the Top500 list of most powerful systems, with 2. 198 exaflops of HPL performance, dethroning America's El Capitan. AI Hypercomputer is a supercomputing system that is optimized to support your artificial intelligence (AI) and machine learning (ML) workloads. It's an integrated system of performance-optimized hardware, open software, ML frameworks, and flexible consumption models.
[PDF Version]
-
Co-packaged photonics remote monitoring system for supercomputing centers
Co-packaged optics (CPO): status, challenges, and solutionsPDF fileCPO Article_EPS_2023_SR_FinalBy leveraging silicon photonics-based optical engines, CPO.
[PDF Version]
-
Dimensions of a 19-inch chassis used in a supercomputing center
EIA-310-D – Defines the official 19-inch rack width, height unit (U) of 1. A 19-inch rack is a standardized frame or enclosure for mounting multiple electronic equipment modules. 6 mm), allowing different hardware from various. How to Choose a 19 Inch Rack Enclosure: Sizes, Types, and Mounting Standards Explained A 19 inch rack enclosure is a rack enclosure that covers servers, switches, patch panels and electronics gear housed in a standard frame. Technically, this 19-inch measurement refers to the width of the front panel of the mountable module that slides into the rack, while the actual server chassis width needs to be less. The rack or cabinet must meet the EIA Standard EIA-310-D for 19-inch racks. The front rack opening must be 451 mm wide + 0. ) apart on center (horizontal width between vertical columns of holes on.
[PDF Version]
-
Micro Modules for Supercomputing Center Computer Rooms
Micro-Module Data Centers: Architecture, Advantages, and. Driven by the "dual carbon" policy and digital transformation, the advantages of micro-module.
[PDF Version]
-
Supercomputing Center Uses AI Servers with Low Loss
AI Hypercomputer is a supercomputing system that is optimized to support your artificial intelligence (AI) and machine learning (ML) workloads. AI factories manage massive workflows and foundational models like LLMs, requiring seamless scaling across thousands of GPUs with ultra-reliable networking to maximize resource utilization. InfiniBand, with ultra-low latency, unmatched bandwidth, and native lossless RDMA performance, has become the. AI Training supercomputing servers are used to teach an AI model to perform specific task. It requires powerful GPU servers and large amounts of data. Key Technologies in Lossless Networking for Distributed SuperComputing Data Centers In heterogeneous networks with asymmetric bandwidth and latency, particularly across long-distance links, collective communication algorithms help adjust traffic flow, reducing congestion. The AI Hypercomputer system. St. Louis, Missouri – November 18, 2025 – MiTAC Computing Technology, a global leader in high-performance and energy-efficient server solutions, is proud to announce its participation at the Supercomputing (SC) 2025 (November 18–20, St.
[PDF Version]
-
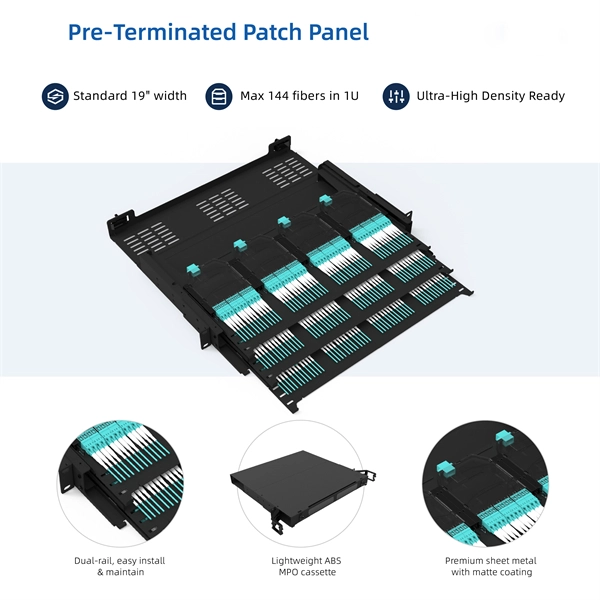
Supercomputing Center Uses Network Cabinets to Resist Electrical Tracking
The series of computers were very early attempts at supercomputing and gained their advantage over the existing systems by relegating work to, freeing the (CPU) to process actual data. With the Minnesota compiler the 6600 could sustain 500 kiloflops on standard mathematical operations.
Fiber and Communications Infrastructure Updates
- Cable tray gantry support
- Types of SC Fiber Optic Patch Cords
- Using single-mode and dual-mode fiber optic cables together
- Explosion-proof boxes and ordinary distribution boxes
- Tools for laying cables in basements
- Fiber distribution box can be connected to fiber distribution box
- Indoor Flexible Optical Cable Splicing Process
- Relay Protection Team Management Issues
- Fiber Optic Cable Distribution Box Regulations
- How to build a chopstick bridge
- Speed Up Mobile Fiber Optic Internet Access